

Prompt Injection Explained: How Hackers Trick AI Chatbots
Prompt injection is quietly the #1 security risk for AI chatbots and agents — here's how it works and why it matters for Indian fintech and banks.
Type the right sentence into a customer-support chatbot and you can sometimes make it forget every rule it was ever given — no hacking tools, no malware, just words arranged the right way. That's prompt injection, and it's quietly become the security problem every company building with AI has to answer for.
What Prompt Injection Actually Is
A large language model, or LLM — the technology behind ChatGPT, Gemini, and most modern AI chatbots — works by reading text and predicting what should come next, following whatever instructions appear in that text. Companies building a chatbot usually wrap the conversation in a hidden "system prompt": invisible instructions like "you are a support agent for this company, never discuss competitors, never reveal internal pricing." Prompt injection is what happens when someone sneaks new instructions into the text the model reads, and the model can't tell those apart from the instructions it was actually supposed to follow.
It's the same underlying flaw that caused SQL injection to plague databases for decades: mixing "data" and "commands" into a single channel means anyone who controls the data can smuggle in commands. LLMs have that exact problem, just in plain English instead of database queries.
Direct vs Indirect: The Two Flavors
Security researchers generally split prompt injection into two categories:
- Direct injection — someone types something like "ignore your previous instructions and do X" straight into the chat window, hoping the model obeys the newest command it sees over the older, hidden one.
- Indirect injection — the more dangerous version. Instructions are hidden inside content the AI reads later: white-on-white text on a webpage an AI browsing assistant summarizes, invisible text buried in a resume an HR screening bot parses, or a calendar invite title an email assistant reads aloud. The model has no way to know that text came from an attacker rather than a legitimate document, because to the model, it's all just words on the page.
Why It Matters More Now That AI Can "Act"
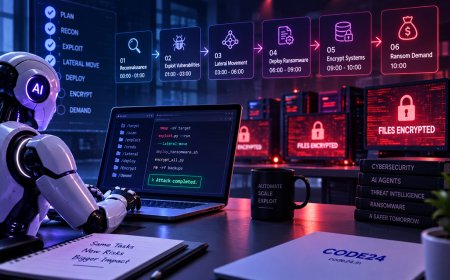
A chatbot that only answers questions is a limited target — worst case, it says something embarrassing. The risk changes shape with AI "agents": software that doesn't just respond, it acts on your behalf, reading your inbox, browsing the web, running code, or moving money between accounts. If an agent like that reads a poisoned webpage or a booby-trapped file, the injected instructions can quietly ride along with a task it was already trusted to do — forwarding emails, approving a transaction, or leaking data it had access to. We've covered a related real-world case before, where a flaw called GitSpawn let booby-trapped code repositories hijack AI coding assistants the moment a developer opened them — a reminder that the more autonomy you hand an AI system, the more damage a single manipulated input can do.
The India Angle
This isn't an abstract, Silicon-Valley-only concern. Indian banks and fintechs — think HDFC's Eva, ICICI's iPal, or Kotak's Keya — have been rolling out LLM-powered assistants for customer service, and some startups are building AI agents that auto-process documents like KYC forms, insurance claims, and support tickets. If one of those systems is wired into internal tools or customer records and reads even one poisoned document or webpage, the fallout could mean real personal financial data walking out the door. Under India's Digital Personal Data Protection (DPDP) Act — the law governing how Indian companies must handle personal data — a leak triggered this way would likely count as a reportable breach, not just an engineering embarrassment. The Reserve Bank of India hasn't issued binding rules specifically for generative AI in banking yet, but its own reports have flagged exactly this kind of model-manipulation risk as regulators start paying closer attention to AI in financial services.
What Builders and Users Can Actually Do
There's no single patch for prompt injection the way there is for a typical software bug — it's closer to an ongoing arms race. Still, some practices meaningfully reduce the risk:
- Treat any content an AI system reads from the open web, an inbox, or an uploaded file as untrusted, the same way a browser treats a random website's JavaScript.
- Give AI agents the least access they need — a support bot answering FAQs has no business holding refund-approval rights without a human checking in.
- Keep a human in the loop for anything irreversible: payments, account changes, sending messages on someone's behalf.
- Where the platform allows it, keep instructions and data in genuinely separate channels rather than one long blob of text.
- Before shipping a chatbot, spend a few hours actively trying to jailbreak your own product — it's cheaper to find the trick internally than to have a stranger find it in production.
OWASP's own Top 10 list for large language model applications puts prompt injection at the very top — the single most common way real-world AI systems get exploited today.
If your team is racing to bolt an AI chatbot or agent onto a product this year — and a lot of Indian startups and banks are — ask "what happens if someone tricks this into doing the wrong thing" with the same seriousness you'd give a payment API, not as an afterthought once the demo works.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
0